About. Supplementary qualitative results for
No Distillation Needed: Single-Pass Real-Time Talking Heads via Acausal Noise Shaping.
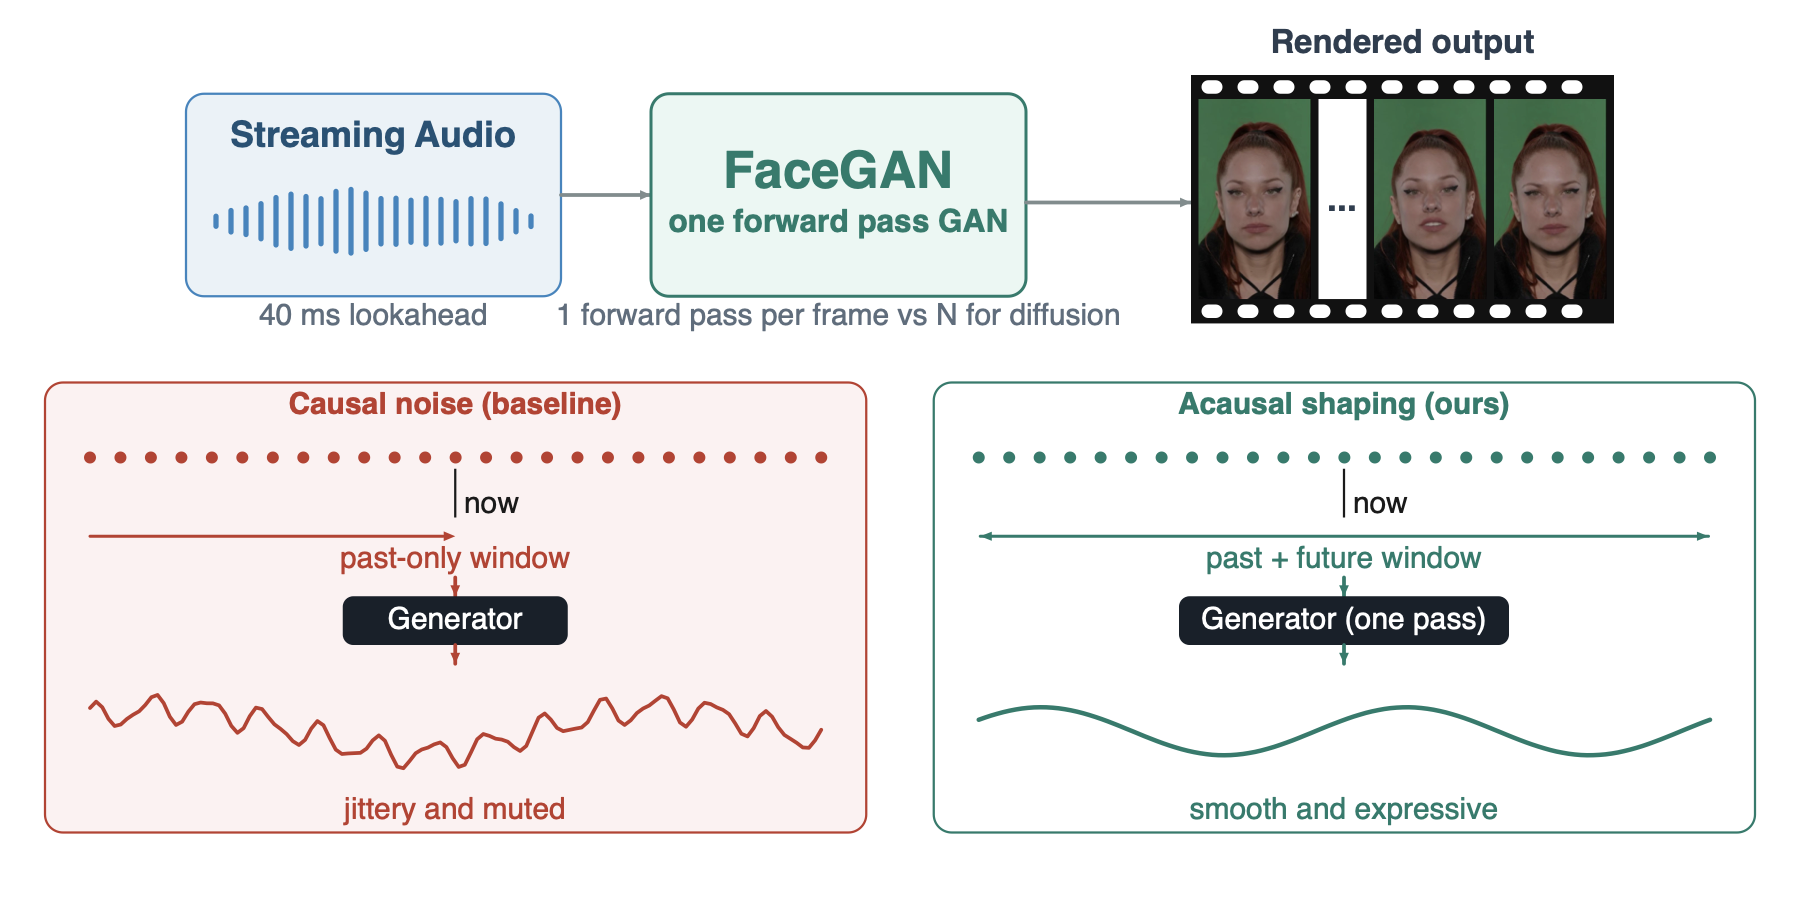
FaceGAN is a streaming single-pass GAN that maps speech to facial expression and head pose
in one forward pass per frame, using latency-free acausal noise shaping to produce smooth,
rich motion without diffusion's iterative sampling cost. Each row compares all methods on
one test clip driven by the same Ground Truth audio.
- Fixed Headpose: switches every row to renders with a fixed neutral head pose, isolating lip articulation and expression from head-motion differences.
- Auto-shuffle clips: randomizes the clip order on each page load (off by default).
- Play / Pause / Restart and the slider control playback of each row.